A Florida woman was arrested over an alleged threat against a sheriff’s office after automated detection, human review, and a police investigation—highlighting the limits of privacy in consumer AI services
A conversation with an AI chatbot has led to a law-enforcement report and the arrest of a user in Florida. A woman in Lee County was arrested after allegedly entering statements into Anthropic’s Claude that threatened an attack on the Lee County Sheriff’s Office.
The incident should not be described as an AI predicting a crime or autonomously identifying a future offender. According to the available reporting, the platform’s safety system detected potentially threatening language. The conversation was escalated to human reviewers, who reported it to law enforcement. Police then identified the user and conducted their own investigation.
The case raises a broader question: when an AI service detects a possible real-world threat, how far should the platform intervene, and how clearly do users understand the circumstances under which their conversations may be reviewed or disclosed?
As chatbots are increasingly used not only for search and work but also as journals and seemingly nonjudgmental conversation partners, the boundary between safety intervention and privacy is becoming a central product-design issue.
From Automated Detection to Arrest
According to WINK News reporting republished by SWFL.io, an arrest report stated that a user identified as “Carli” wrote on September 26, 2026, that she intended to attack the Lee County Sheriff’s Office. Investigators said the same user wrote the following day that she had obtained a new gun.
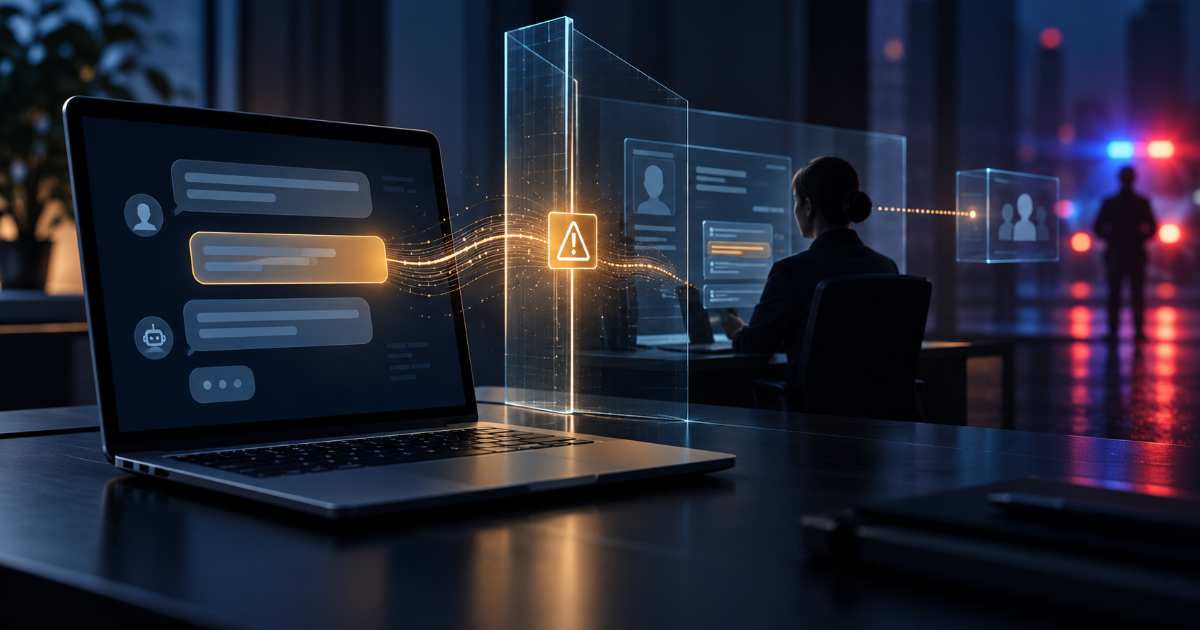
The report said Anthropic’s platform uses safety and security measures to monitor for key phrases and potentially threatening content. Because of the severity of the statements, the conversation was escalated to a human review team, which reported the content to law enforcement.
Deputies detained the woman at her home in Bonita Springs. She was charged under Florida law with making a written threat of violence.
Lee County Sheriff Carmine Marceno said the woman later described using AI like a diary. That statement, however, was relayed by law enforcement and should not be treated as a judicial finding. The currently established facts concern the arrest and the charge. Whether the messages reflected a genuine operational plan, what broader context surrounded them, and whether the charge will ultimately be sustained remain matters for the legal process.
The public record also does not reveal the complete conversation, the precise threshold used by the safety system, the human reviewers’ criteria, or the exact information shared with police. The episode therefore cannot support a broad conclusion that an AI system accurately predicted a crime.
A Chain of Automated and Human Decisions
The central feature of the case is not autonomous crime prediction but a sequence of decisions. An automated system identified language associated with possible danger. A person reviewed the conversation and decided to report it. Police then conducted a separate investigation and made an arrest.
The distinction matters because an automated classifier cannot be assumed to understand intent perfectly. Similar violent language may appear in a genuine threat, fictional writing, a news summary, a quotation, or an emotional outburst. A system that relies too heavily on isolated language can miss a real danger or escalate a conversation that presents no actual threat.
Human review does not automatically guarantee accuracy. It does, however, indicate that the reported case was not handled solely on the basis of an automated score. The incident is better understood as a multi-stage safety process than as an AI making an independent law-enforcement decision.
Anthropic’s 2026 Usage Policy update, announced on October 8 and scheduled to take effect on November 12, explicitly states that Claude cannot be used to decide or recommend whom to investigate, arrest, or charge. It also requires qualified human oversight when AI recommendations may affect an individual’s legal rights or other high-risk interests.
Those restrictions do not mean an AI company is prohibited from using internal systems to detect dangerous content. Platform safety monitoring and the use of an AI model to select law-enforcement targets are distinct activities.
Encrypted Does Not Mean Inaccessible Under Every Circumstance
The conversational nature of AI services can create the impression of a private space. A chatbot, however, should not be treated as equivalent to a personal notebook or a legally privileged conversation with a doctor or attorney.
Anthropic says consumer Claude data is encrypted in transit and at rest and that employees cannot access conversations by default. It identifies exceptions, including when a user voluntarily shares data as feedback and when review is required to enforce the company’s Usage Policy. In the latter case, Anthropic says access is limited to designated Trust and Safety personnel on a need-to-know basis.
Anthropic’s privacy policy, effective September 10, 2026, states that personal data may be processed to detect and investigate fraud, abuse, policy violations, illegal activity, and threats to safety. It also says information may be shared with government or law-enforcement bodies when the company believes disclosure is reasonably necessary to prevent serious harm to a person or property.
A separate policy for government requests says Anthropic generally requires valid legal process, such as a subpoena or warrant. It provides an exception when the company believes an emergency may result in imminent physical harm or death and prompt disclosure could help prevent it.
These policies do not establish that employees routinely read every conversation or that minor statements are automatically sent to police. They also do not support the assumption that a chatbot conversation is an absolutely confidential space. The relevant point is that conversations may be flagged for safety enforcement, reviewed by authorized personnel, and disclosed in limited emergency circumstances.
The Ban on “Abusing AI” Is a Separate Issue
The arrest has circulated alongside reports that Anthropic has prohibited users from insulting or abusing its models. The two issues should not be conflated.
Anthropic’s October 8 policy update adds a prohibition on “sustained and needless abusive or cruel behavior” toward its models. The company says the rule is intended for extreme cases in which users repeatedly act cruelly toward a model without a discernible purpose. It explicitly excludes ordinary frustration, disagreement, dark creative material, and legitimate model testing or research.
Anthropic also says the primary enforcement mechanism will be Claude’s ability to end a rare conversation involving persistent abuse. The announcement does not say that ordinary insults will lead to police reports or automatic account termination.
The Florida case involved alleged language describing violence against a real institution, not merely disrespectful language directed at an AI model. Treating the model-abuse rule and emergency safety reporting as a single policy obscures the actual issue.
What the Case Means for Users, Developers, and Platforms
Users should recognize that information entered into a consumer chatbot is processed on the provider’s systems and may be subject to safety review. Sensitive personal, health, or legal information should be handled with an understanding of the service’s privacy and usage policies. At the same time, being flagged by a classifier must not itself be treated as proof of criminal intent.
Developers need to consider disclosure as part of safety design. Users should be told, in understandable terms, what categories of content may trigger automated detection, when human reviewers may become involved, and under what conditions information may be shared externally. Procedures for addressing false positives and principles for limiting disclosure to necessary information are also important.
Platforms face a wider transparency challenge. Some degree of monitoring and escalation may be necessary to address credible threats, but broad or opaque standards can leave users unable to understand how their conversations are handled. Aggregate reporting on safety flags, human reviews, external disclosures, false positives, and appeals could provide a basis for evaluating whether these systems are effective and proportionate.
This case is not evidence that AI has begun identifying criminals before they act. It shows instead that as people share more personal thoughts and emotions with AI, platforms must define when a conversation remains private and when safety concerns justify intervention. The critical test will not simply be whether reporting mechanisms exist, but whether the standards connecting automated detection, human judgment, and law enforcement are sufficiently transparent and accountable.