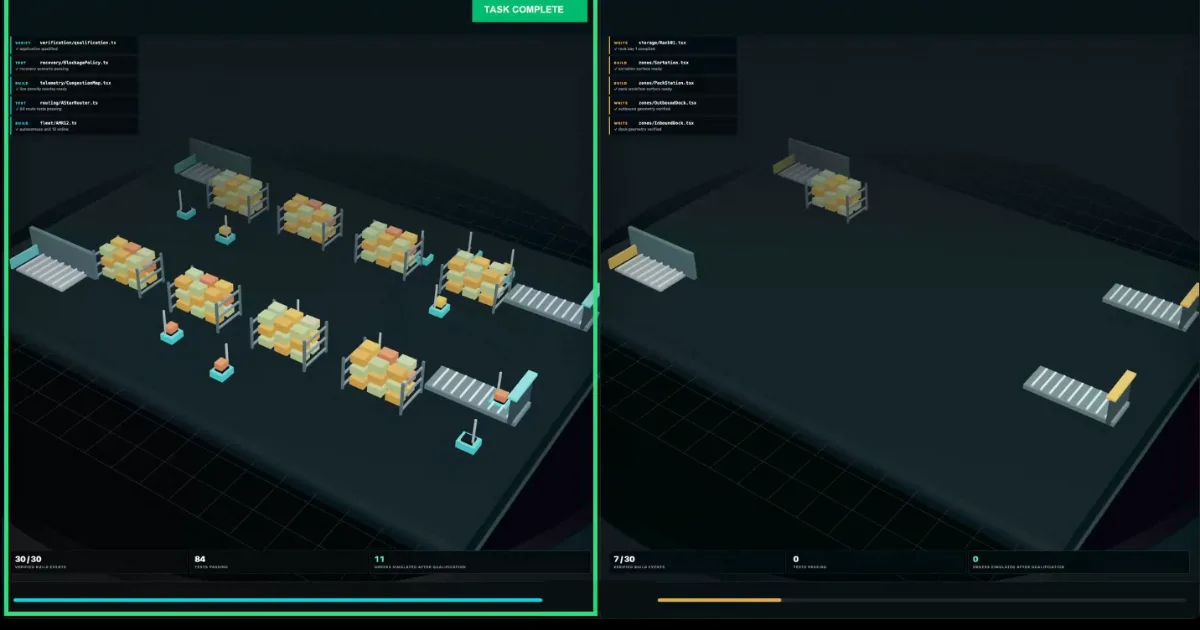
OpenAI has introduced a new service tier called Ultrafast, designed to run GPT-5.6 Sol up to 14 times faster than standard processing.
On August 13, 2026, OpenAI announced an early preview of Ultrafast. The tier first became available through the OpenAI API. Powered by Cerebras infrastructure, it can generate up to 750 output tokens per second.
In simple terms, OpenAI is trying to shift the competitive axis of frontier models again.
Until now, high-performance AI models have often been seen as smart but slow. Complex reasoning, long-context understanding, multi-step tool use, code writing and research analysis take time. For products where real-time response matters, companies often had to choose smaller models or models optimized for narrow tasks.
OpenAI is trying to reduce that tradeoff.
The premise it wants to challenge is this: if you want faster AI, you must choose a less intelligent model.
If a top-tier model such as GPT-5.6 Sol can be delivered at near-real-time speed, the range of work AI can enter changes.
The core point is not simply faster output.
OpenAI’s key phrase is “more useful work per second.”
That means the competition is shifting from accuracy and benchmark scores to how many judgments and actions a model can complete inside real working time.
Why Speed Has Become as Important as Intelligence
AI model competition has long been a competition over intelligence.
Who can solve harder math problems?
Who can write longer code?
Who can understand more complex documents?
Who can score higher on benchmarks?
But in enterprise work, intelligence alone is not enough.
Time is value.
During a system outage, the correct answer ten minutes later may be too late. In customer support, an AI that remains silent for 30 seconds loses usefulness. In financial markets, a few seconds can change the meaning of a decision. In online commerce, answers must arrive while the shopper is still considering a purchase.
A model can be intelligent and still fail to enter the workflow if it is too slow.
That is why companies have had to choose between fast models and smart models. Complex problems went to larger models. Real-time products used smaller models. In that structure, the harder the user’s question, the more latency increases, and the product experience breaks.
Ultrafast targets this bottleneck.
It tries to put frontier intelligence into real-time products.
If that becomes possible, AI moves from a back-office analysis tool to a front-line work tool. It enters not only tasks where people can wait, but also situations where people will not wait.
Incident Response: Narrowing the Cause While the Outage Is Still Happening
One of OpenAI’s key use cases is incident response and reliability.
When a system outage occurs, engineers must look at many signals at once: application logs, recent code changes, deployment history, alerts, traces, monitoring metrics and conversations among engineers. The challenge is that this information is not static. During the incident, logs keep growing, hypotheses change and new signals arrive.
If AI is slow in this situation, its usefulness is limited.
Incident response is not the work of summarizing an event after it is over. While the outage is still unfolding, engineers must narrow the cause, identify the next checks, prepare possible fixes and decide whether to deploy.
OpenAI says it has tested Ultrafast internally for incident response. When alerts fire, developers use it to read logs, analyze traces, synthesize conversations, identify next checks and prepare or verify fixes. The important caveat is that engineers still retain judgment and deployment responsibility.
That shows the realistic direction of AI operations automation.
AI may not automatically fix and deploy a patch.
Instead, it reduces the delay between signal observation, hypothesis testing and the next action. It does not replace human judgment. It shortens the path to judgment.
In incident response, speed reduces damage.
That is why Ultrafast matters.
Finance and Security: Markets and Risks Do Not Wait
OpenAI also presents financial research and security as use cases for Ultrafast.
Financial markets move in real time. News, prices, trading volume, company disclosures, macroeconomic data and social signals change quickly. Security is similar. Suspicious transactions, account takeovers, anomalous behavior and network signals can turn into damage if too much time passes.
In these domains, AI is not merely a summarization tool.
It must analyze market signals, evaluate trades, identify suspicious activity and support judgment under changing conditions. A slow model may help write a post-event report, but it is less useful for live response.
Rogo’s Applied AI lead said Ultrafast makes complex financial research feel like real-time interaction. That changes the experience of financial research. Instead of running analysis overnight and receiving a report the next day, an analyst can ask a question, receive a result immediately, change the conditions and reanalyze in conversation.
Security follows the same logic.
Analyzing a suspicious transaction minutes later is different from evaluating risk while the transaction is still happening. Reading logs while an attacker is moving is different from writing a forensic report after the incident.
Ultrafast’s message is clear.
For AI to enter time-sensitive work, it cannot only be smart.
It must be fast.
Customer Support and Voice AI: Conversation Cannot Break
Customer support and voice AI reveal the speed problem most directly.
Users do not wait patiently during a conversation. In voice support especially, long silence breaks the experience. A simple FAQ can be handled by a small fast model. But real customer issues are complicated. The system may need to check order history, retrieve policy, inspect system status, judge exceptions and suggest a resolution path.
That requires a model that is both fast and intelligent.
Podium’s Voice AI product lead described Ultrafast as highly valuable in the voice stack and said its speed changed the call experience for complex workflows.
This shows why latency is central if voice AI is to move from simple response bots to actual problem-solving agents.
One second is long in voice interaction.
If users must wait while the model queries systems and reasons through a problem, the conversation no longer feels natural. But if a frontier model can handle complex issues at real-time speed, the scope of customer support automation expands significantly.
Until now, companies have had to compromise between speed and accuracy in customer support. Fast chatbots are good at simple questions but weak on complex problems. Smart models are good at complex problems but slow. Ultrafast tries to close that gap.
The competitive edge in customer support AI is no longer only answer quality.
It is the ability to maintain conversational rhythm.
Commerce: Answer Before the Cart Is Abandoned
In commerce, speed connects directly to revenue.
A shopper viewing a product may wonder whether it is in stock, when it will arrive, whether it fits their situation, how it differs from another product or why a payment failed. If the answer comes too late, the shopper hesitates and leaves.
OpenAI says Ultrafast can answer product questions, check inventory, personalize recommendations and resolve checkout problems. The key is answering while the shopper is still deciding.
This shows how the role of commerce AI is changing.
Traditional recommendation systems mainly showed products.
Chatbots mainly handled inquiries.
High-speed frontier models can enter the middle of the purchase decision as real-time advisers.
If a shopper asks, “Can this laptop handle video editing?”, “Will this size fit me?”, “Can I receive this by this week?” or “Why isn’t this coupon applying?”, the model must consider product information, inventory, shipping, user context and policy at the same time.
If it is slow, the sale may be lost.
To increase conversion, commerce AI must be accurate.
But it must also arrive inside the purchase flow.
Ultrafast is aimed at that real-time window.
Research and Experimentation: Overnight Loops Move Into Working Hours
Another important use case is live research and experimentation.
Research work is a loop. Form a hypothesis. Gather data. Run an experiment. Review results. Revise the hypothesis. In many organizations, that loop moves in daily cycles. A batch experiment runs overnight. The results are reviewed the next morning. The next experiment is then designed.
OpenAI says Ultrafast can compress this loop into multiple iterations during working hours. It can search knowledge sources, query data and gather, organize and summarize information across connected tools.
That has major implications for research productivity.
When systems are slow, users gather questions carefully and submit them in batches. When systems are fast, users think in conversation. They ask, see the result, adjust immediately and continue to the next experiment.
Fast AI helps users maintain flow.
This is not only time savings.
It changes the way people think.
Moving from overnight batch processing to interactive loops allows researchers to test more hypotheses, find failures faster and revise ideas more often.
This is where “more useful work per second” becomes most meaningful.
It is not only that the token count per second increases.
It is that the number of possible learning loops per day increases.
What the Cerebras Partnership Means
Ultrafast is powered by Cerebras.
OpenAI describes this as the next phase of its partnership with Cerebras. Cerebras provides ultra-low-latency inference on the OpenAI platform, supporting GPT-5.6 Sol Ultrafast at up to 750 output tokens per second.
This shows how AI infrastructure competition is changing.
Model competition is no longer only about the model file. It is also about which hardware runs the model, which inference stack is used, what latency and cost are possible and how close the service can come to enterprise-level reliability.
Enterprise customers do not simply want the smartest model.
They want speed, reliability and cost structures that can fit inside products.
Cerebras plays a strategic role here.
GPU infrastructure alone may not solve every requirement. For workloads where ultra-low latency and high output-token throughput matter, specialized inference infrastructure can become a competitive advantage. OpenAI’s decision to offer a frontier model such as GPT-5.6 Sol through Cerebras-based Ultrafast is an infrastructure strategy to expand frontier AI into real-time products.
The AI industry is now competing across three layers at once:
model capability;
inference cost;
and real-time throughput.
Ultrafast packages those layers together.
Fast Mode and Ultrafast Are Different
OpenAI already offers Fast mode for API customers.
Fast mode provides up to 2.5 times faster performance for gpt-5.6-sol compared with standard speeds. Ultrafast is a more aggressive speed tier.
If Fast mode is an option for improving latency on existing API workloads, Ultrafast is being positioned as a new speed class powered by Cerebras, with up to 14 times standard speed and up to 750 output tokens per second.
The difference is not only technical.
It is product positioning.
Fast mode improves existing API use cases.
Ultrafast is meant to enable new types of products and workflows.
The target areas are real-time voice, incident response, financial research, commerce and live experimentation—domains where speed determines whether AI can be used at all.
This also matters for OpenAI’s API business.
As token-price competition becomes more intense, differentiation cannot depend only on price per token. OpenAI is giving enterprise customers a more segmented set of choices across model intelligence, cost efficiency and speed tiers.
The API market may become not only a question of which model to use.
It may also become a question of which speed class to use.
What Early Customers Are Saying
OpenAI has highlighted early customer examples including Jane Street, Podium, Basis and Rogo.
Jane Street described the speed improvement from Cerebras as impressive and said it enables different ways of working with models. Podium emphasized the value of Ultrafast in its voice stack. Basis said the barrier to fast products is not only tokens per second, but also model intelligence. Rogo said speed does not only make a product feel better; it changes what people can realistically use the product for.
The common theme is that speed changes function.
Slow AI is a post-event analysis tool.
Fast AI is a real-time collaborator.
Slow AI fits work where users can wait.
Fast AI enters work where users do not wait.
Basis’s point is especially important.
Many people think of speed in AI products only as tokens per second. But if the model is not intelligent enough, a fast answer still may not be useful. If the model is intelligent but too slow, the product experience breaks.
Ultrafast’s claimed advantage is the combination.
Intelligence and speed together.
That is the essence of OpenAI’s new speed class.
The Hidden Bottleneck in Enterprise AI Is Waiting
In enterprise work, the hidden bottleneck of AI adoption is waiting.
A user asks a question and waits.
A developer waits for analysis.
A support agent waits for system output while a customer is on the line.
A researcher waits overnight for experiment results.
A security team waits for log analysis and risk assessment.
If AI reduces that waiting, it changes more than efficiency.
It changes work design.
An incident commander can ask the model to compare recent deployments with error logs and immediately move to the next check. A financial analyst can ask the model to update risk scenarios based on new market data and continue iterating conversationally. Customer support can handle complex issues without leaving the customer in silence.
When waiting decreases, AI moves from outside the workflow to inside it.
Speed is not merely perceived quality.
It is the entry ticket into live work.
Safety and Responsibility
Fast frontier models also create new responsibilities.
The faster AI answers, the more it can influence real-time work. Incident response, financial security, customer support, commerce and research experimentation are high-impact domains. If a fast model spreads a wrong judgment quickly, the harm may also accelerate.
OpenAI’s internal incident-response example keeps engineers responsible for judgment and deployment. That matters.
Even if Ultrafast is very fast, real-world action must remain inside organizational processes.
In incident response, AI may propose a fix, but humans should decide whether to deploy. In finance and security, an AI risk judgment that triggers automatic blocking or transaction denial must account for false positives. In customer support, fast incorrect policy guidance can damage trust. In commerce, excessive personalization or inappropriate recommendations can create problems.
Speed is a double-edged sword.
Good judgment delivered quickly creates value.
Bad judgment delivered quickly creates risk.
As Ultrafast-like services spread, companies must design not only for response speed, but also for approvals, logs, audits, human intervention points and responsibility boundaries.
What Korean Companies Should Notice
Ultrafast also matters for Korean companies.
Many companies have adopted generative AI, but use cases often remain in relatively asynchronous and lower-risk areas such as report writing, summarization, translation, chatbots and coding assistance. One reason is speed. Complex models have often been too slow for real-time customer experience or operational response.
If speed tiers such as Ultrafast become common, the scope of adoption may change.
Telecom companies can use AI for incident response and network-log analysis.
Financial institutions can use it for suspicious-transaction detection and real-time research support.
Retail companies can provide real-time product consultation while customers are still deciding.
Manufacturers can analyze equipment logs and quality data in near real time.
Contact centers can resolve complex inquiries during voice calls.
Research organizations can compress day-long experiment cycles into hour-level loops.
But before adoption, Korean companies should check several things.
First, distinguish work that truly needs fast response from work that does not. Not every task needs Ultrafast.
Second, calculate the value of the speed premium. Ultra-low latency should be tied to revenue, recovery time, customer satisfaction or experimentation speed.
Third, build accountability systems for real-time AI judgment. In finance, healthcare, security and public-sector contexts, human approval and audit logs are essential.
Fourth, design data connections. Ultrafast is valuable only if the model can quickly access logs, knowledge bases, inventory, customer information, code changes and experiment data.
Fifth, change work processes. If a fast model is introduced but humans still review outputs on a daily cycle, the benefit is limited.
AI speed innovation does not end with changing the model.
It requires changing how the organization works.
AI Value Will Be Measured by How Much Work It Completes per Second
OpenAI’s Ultrafast preview shows the next competitive axis of the AI industry.
GPT-5.6 Sol is one of OpenAI’s top models. Ultrafast runs that model up to 14 times faster than standard processing and, through Cerebras infrastructure, can generate up to 750 output tokens per second. It is first available through the OpenAI API for limited customers, with access expanding as capacity grows.
The essence of the announcement is speed.
But the point is not merely that answers arrive faster.
A faster frontier model changes where AI can be used. It can analyze logs while an incident is happening, resolve complex problems while a customer is on a call, provide inventory and recommendations before a shopper abandons the cart, support financial research while markets move and turn overnight research loops into repeated iterations during the workday.
Until now, AI competition has mostly asked one question:
Who is smarter?
The question is changing.
Who can deliver a smarter model faster?
Who can put frontier intelligence into real-time products without sacrificing capability?
Who can complete more useful work per second?
That is why OpenAI frames Ultrafast as a new speed class for frontier intelligence.
When frontier intelligence gains real-time speed, AI moves from after-the-fact analysis to immediate operational support. But responsibility grows as well. Fast judgment can also mean fast error. Companies must therefore design verification, approval, audit and accountability systems together with speed.
The next battleground in AI is not only the answer.
It is the time it takes to reach the answer.
More precisely, it is how much real work can be completed inside that time.