Title: A Foundation Model to Predict and Capture Human Cognition
Authors: Marcel Binz, Elif Akata, Matthias Bethge, et al.
Journal: Nature, Vol. 644, pp. 1002–1009
Year: 2025
DOI: 10.1038/s41586-025-09215-4
Can generative AI go beyond speaking like a person and predict what real people will choose? A research team led by Helmholtz Munich developed Centaur, an AI model designed to predict human behavior across a wide range of psychological experiments. Rather than assessing whether the model could merely generate plausible or human-sounding answers, the researchers tested how accurately it could reproduce the choice patterns observed among real participants.
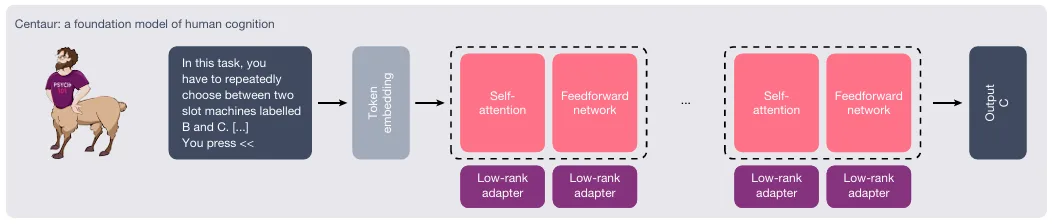
The researchers created a large-scale dataset called Psych-101 by converting trial-by-trial records from 160 psychological experiments into natural-language sequences.
Source: Binz et al. (2025), Fig. 1.
The dataset contains data from 60,092 participants and 10,681,650 individual choices. It covers diverse cognitive tasks, including decision-making, memory, reinforcement learning, supervised learning, multi-armed bandits and Markov decision processes.
Centaur was created by fine-tuning the open-source Llama 3.1 70B model on Psych-101. The researchers used quantized low-rank adaptation, or QLoRA, which added a relatively small number of trainable parameters while leaving the underlying language model largely unchanged. The model was specifically trained to predict the human responses recorded in each experimental sequence.
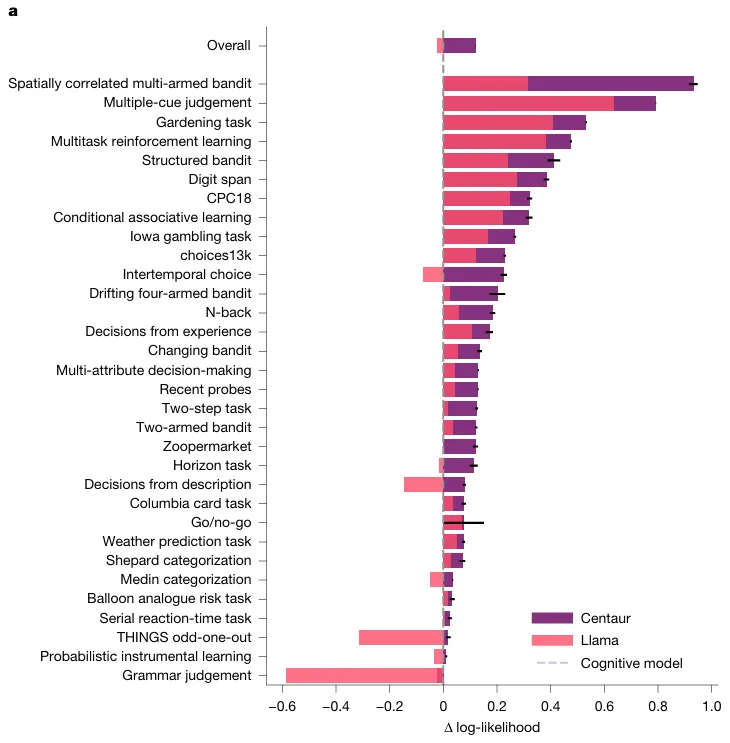
The results showed that Centaur predicted the choices of previously unseen participants more accurately than both the original Llama model and most domain-specific cognitive models.
Psych-101 experimental data were converted into natural-language sequences and used to fine-tune Llama 3.1 70B with low-rank adapters to predict subsequent human choices.
Source: Binz et al. (2025), Fig. 1b.
In the main evaluation, 90% of the participants from each experiment were used for training and the remaining 10% were held out for testing. Centaur achieved a lower average negative log-likelihood than Llama and the conventional cognitive models, indicating a better fit to actual human responses.
Centaur did more than repeat patterns from tasks included in its training data. It continued to predict human choices when the narrative setting of an experiment was changed, when the number or structure of the available choices was modified, and when it was tested in cognitive domains that had not appeared in Psych-101. These new domains included logical reasoning, moral decision-making, economic games and naturalistic learning tasks.
The researchers also examined nearly four million response-time measurements. The uncertainty estimated by Centaur explained a larger proportion of the variation in human response times than estimates produced by either the base Llama model or conventional cognitive models. This suggests that Centaur captured not only which option people were likely to select, but also some of the patterns associated with how quickly they made their decisions.
Two existing fMRI datasets were also used to examine the relationship between the model’s internal representations and human neural activity. One dataset involved 94 participants performing a sequential decision-making task, while the other involved five participants reading diverse sentences. Across these analyses, Centaur’s internal representations were generally more predictive of human neural activity than those of the original Llama model.
However, this finding does not mean that Centaur thinks in the same way as the human brain.
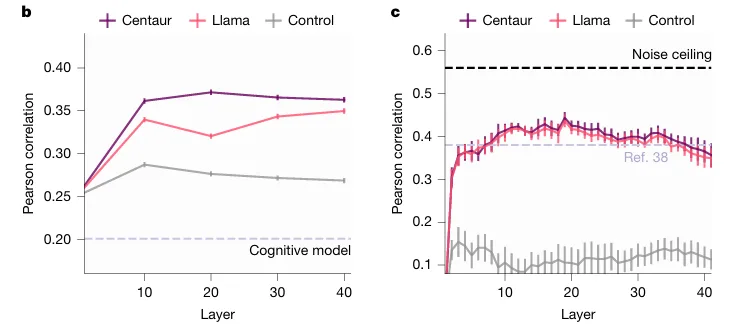
It only shows that the representations produced by a model fine-tuned on human behavioral data were more useful for predicting certain neural measurements. Similarity in behavioral or neural prediction is not proof that humans and AI rely on identical cognitive mechanisms.
Does This Mean AI Can Replace Human Participants?
The study should not be interpreted as evidence that AI can immediately replace real participants in psychological experiments. Centaur is not an AI persona that reproduces the personality, experiences and decision patterns of one particular individual. It is better understood as a population-level predictive model that has learned recurring patterns from a large collection of human behavioral experiments.
The current version of Psych-101 is also concentrated primarily on learning and decision-making. It includes limited information about individual characteristics such as age, personality, socioeconomic background and psychological condition. The dataset also contains a strong bias toward Western, educated, industrialized, rich and democratic populations, commonly described as WEIRD populations.
Furthermore, predicting outcomes similar to those produced by humans does not mean that the AI is reasoning in the same way as a human. The original paper does not present Centaur as a completed theory of cognition. Instead, the authors argue that the next step is to translate such a broad predictive model into a unified and interpretable theory of human cognition. A related Nature News & Views article similarly frames these machine-learning approaches as opportunities for connecting theories that have traditionally remained separated across cognitive domains and levels of analysis.
The Question Raised by This Study
The true significance of Centaur does not lie in the claim that AI can replace people. Traditionally, researchers designing a new survey or behavioral experiment could evaluate its likely outcomes only after recruiting actual participants and collecting data. A sufficiently validated human-behavior model could instead allow researchers to test questions, experimental conditions and scenarios virtually before conducting the main study.
Such a model could help researchers identify unclear questions, compare alternative experimental designs, estimate potential effect sizes and determine which conditions deserve further investigation. The Centaur researchers specifically suggest that the model could be used for in silico prototyping, including exploring designs that might increase effect sizes, reduce the number of required participants or improve statistical power.
The next question for AI personas and silicon sampling is therefore no longer simply:
Does the AI answer like a human?
A more important question is:
How accurately does the AI reproduce real human behavior, and under what conditions can its predictions be trusted?
Centaur shows that research on AI-based experimental participants is moving beyond role-playing prompts and human-like conversation. The field is beginning to emphasize models trained on real behavioral data, evaluated against external human samples and tested across situations that differ from those included in training.
Centaur is not yet a substitute for real participants. It is better understood as a potential tool for pretesting research designs, generating hypotheses and identifying conditions that should later be verified through studies involving actual people.