1. Is Publication Alone Enough to Trust a Finding?
When a study is published in a peer-reviewed journal and reports a statistically significant result, how much confidence should we place in it?
Scientific knowledge does not become reliable simply because an effect appears once. Confidence grows when independent researchers can test the same claim again and obtain compatible evidence.
This leads to the central question of the review:
Will a published finding hold up when independent researchers test it again?
2. Replicability Is Not the Same as Reproducibility
Two related terms should first be distinguished.
Reproducibility asks whether the same conclusion can be obtained by reanalyzing the original data, methods, and code.
Replicability asks whether a previous conclusion can be supported using new or independent evidence.
The study reviewed here focuses primarily on replicability. Instead of merely rerunning existing analyses, the researchers independently tested previously published claims.
3. How Were 274 Claims Retested?
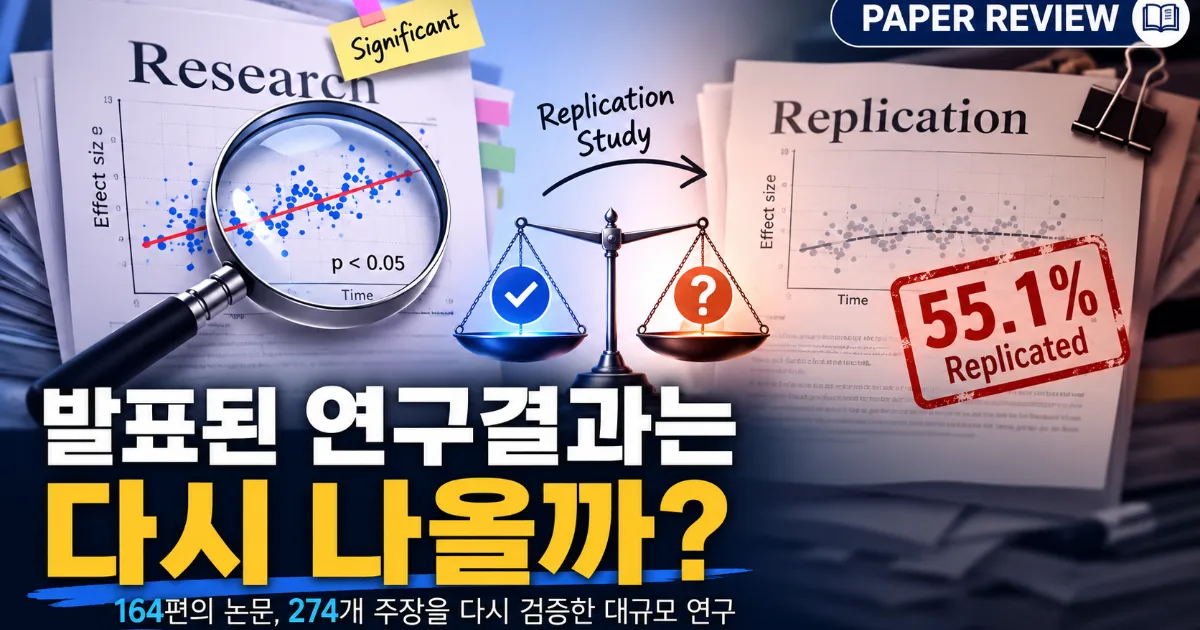
The research team selected 274 positive claims from 164 quantitative papers published between 2009 and 2018 across 54 journals in the social and behavioral sciences.
The replication studies were designed with high statistical power. The median power to detect the originally reported effect was 99.6%. Whenever possible, the teams used the original materials, and replication plans were reviewed in advance through a standardized internal protocol.
This design matters because the project was not a casual attempt to discredit earlier studies. It was a coordinated effort to give the original claims a rigorous and fair independent test.
4. The Original Pattern Reappeared in 55.1% of Claims
Of the 274 claims, 151 produced a statistically significant result in the same direction as the original finding. This corresponds to a replication rate of 55.1%.
After weighting the results to account for papers that contributed more than one claim, the paper-level estimate was 49.3%. Replication rates across disciplines ranged from approximately 42.5% to 63.1%, although some disciplinary estimates involved substantial uncertainty.
These numbers may tempt readers to conclude that “half of social science is wrong.” However, that would oversimplify both the study and the meaning of replication.
5. Replicated Effects Were Also Smaller
The median effect size in the original studies was Pearson’s r=.25. In the replication studies, it fell to r=.10. The authors described this as an 82.4% reduction in shared variance.
Several mechanisms may help explain this decline.
Positive and statistically significant findings are more likely to be published than null results. Initial effect estimates may also be inflated by sampling variation. In addition, effects can change across populations, cultures, time periods, measurements, and research settings.
A smaller replication effect therefore does not automatically show that the original researchers made an error. It shows that the magnitude reported in one study should not be assumed to generalize unchanged.
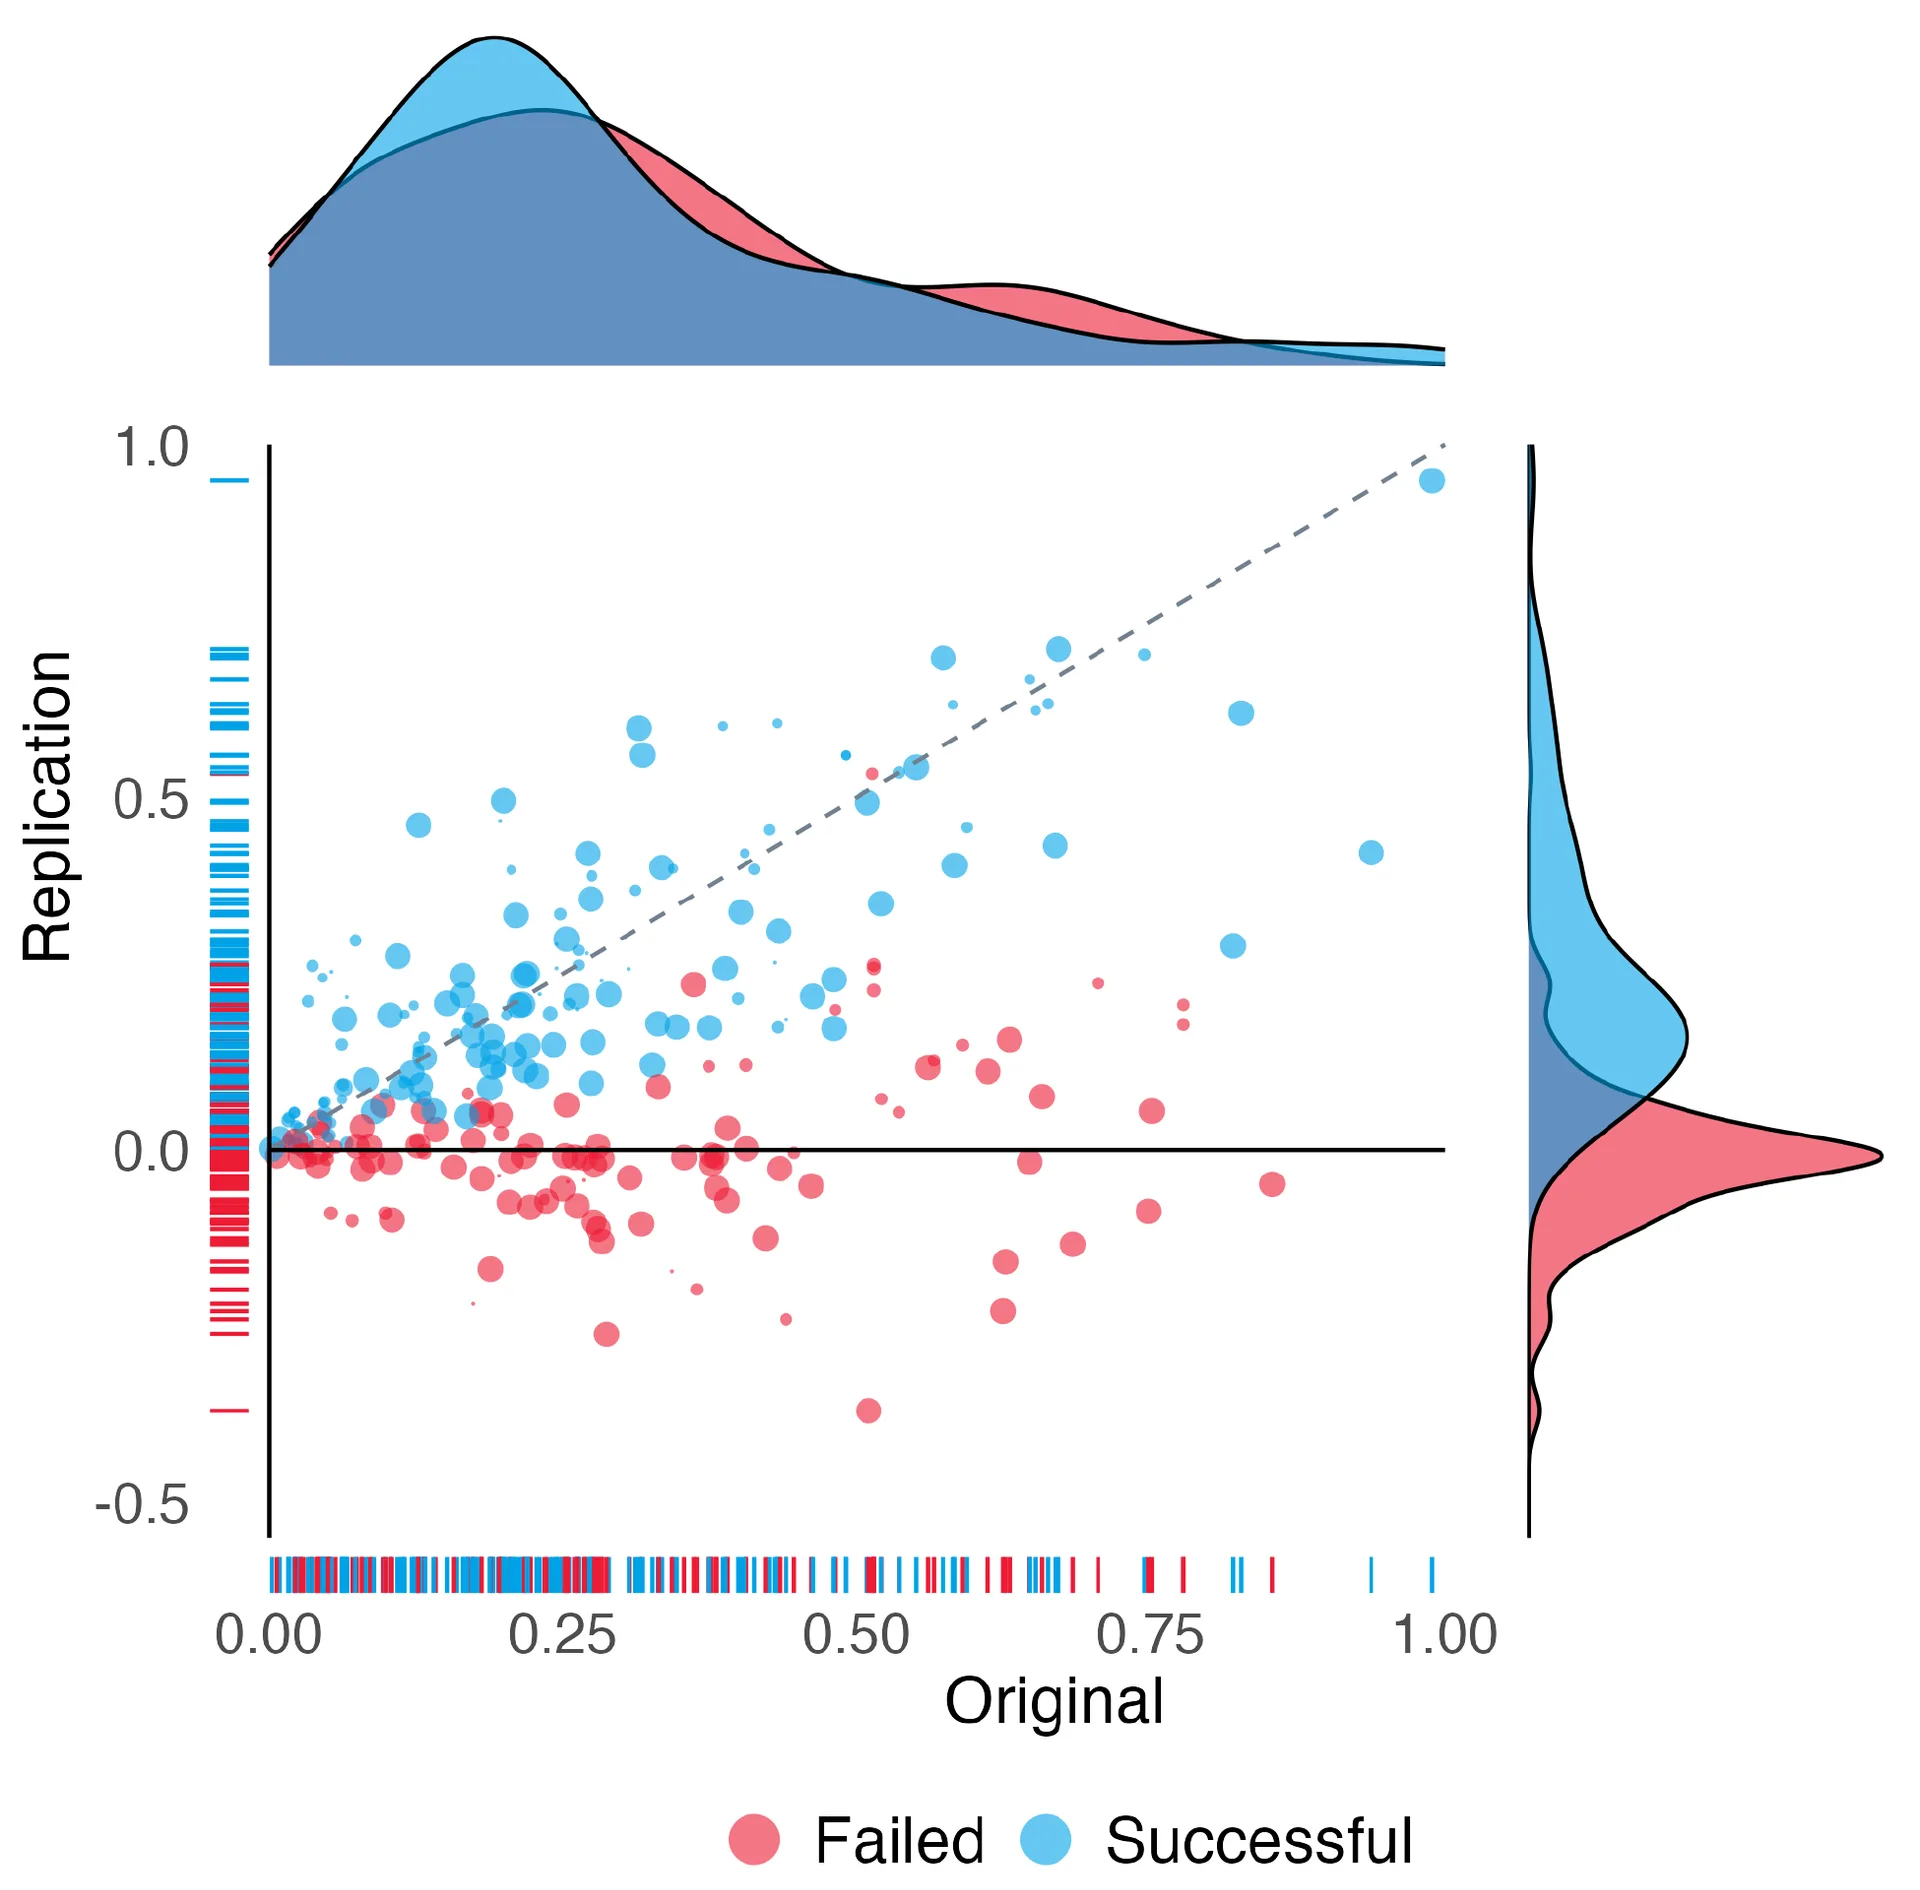
Each point represents a replicated claim. Points below the diagonal indicate that the replication effect was smaller than the original effect. Blue points denote statistically significant results in the original direction, whereas red points denote non-significant or opposite-direction results.
6. Does a Failed Replication Prove That the Original Study Was False?
This is the most important interpretive caution.
The project selected positive findings for replication, so some decline in statistical significance and effect size was expected because of statistical power and regression to the mean. The estimated success rate also depended heavily on the definition used: across 13 assessment methods, replication estimates ranged from 28.6% to 74.8%, with a median of 49.3%.
A failed replication should therefore not be translated directly as:
“The original claim was false.”
A more accurate interpretation is:
“Under the conditions of this replication, the available evidence did not confirm the original claim with the same strength.”
Replication is not a final verdict on truth. It is a process of updating confidence by adding independent evidence.
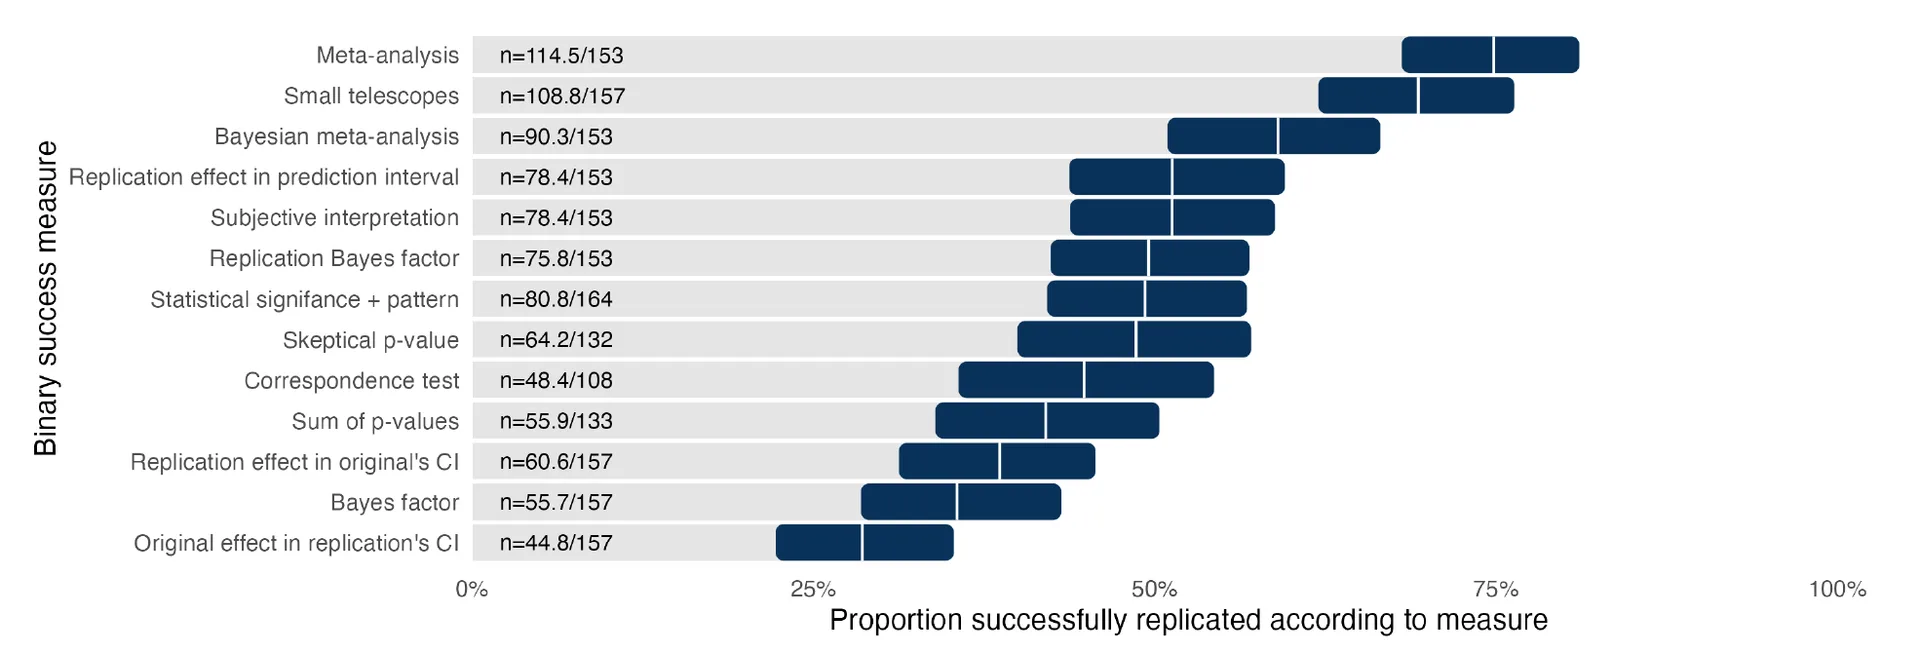
Paper-level estimates of replication success ranged from 28.6% to 74.8% across 13 assessment methods, with a median of 49.3%.
7. Trust Comes from a Verifiable Research Process
The paper is not an argument for distrusting science. It is an argument for making scientific claims easier to examine, challenge, and improve.
Practices that can strengthen scientific credibility include:
preregistering hypotheses and analysis plans;
sharing data, code, and research materials;
using adequately powered samples;
reporting null and inconclusive findings;
distinguishing exploratory from confirmatory analyses; and
giving replication studies greater academic value.
The data, materials, and code associated with this project were also made available through an open repository. This reflects a broader principle of open science: researchers should make not only their conclusions but also the path leading to those conclusions open to inspection.
8. Conclusion: Good Science Is Not Science That Never Fails
It would be misleading to summarize this study by saying that half of social and behavioral science is false.
Its deeper message is that scientific knowledge is not completed by one paper, one experiment, or one statistically significant result. Reliable knowledge emerges as researchers repeat tests, compare outcomes, investigate disagreements, and accumulate evidence across studies.
Good science is not science that never gets things wrong. It is science that makes its claims open to correction and independent verification.