Alibaba introduces Qwen-Audio-3.1-TTS-Next, a model designed to turn a written scene into a complete audio sequence
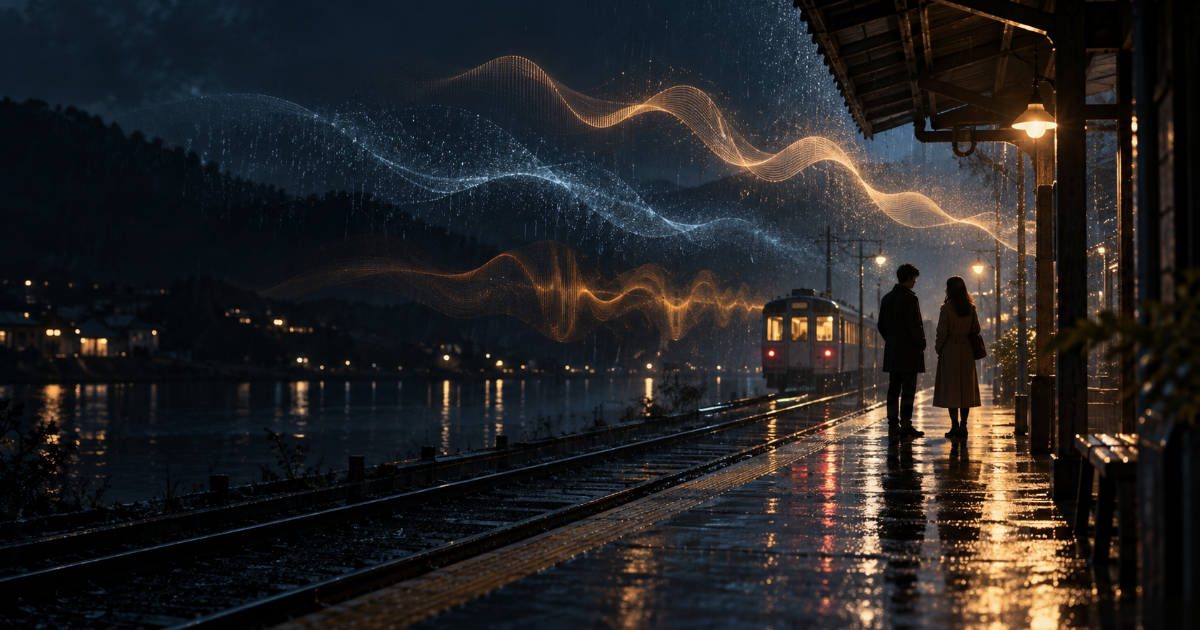
Rain falls on a railway platform at night. Two people exchange a few words. Between their lines, a train rumbles in the distance and a departure signal sounds. As one person turns away, their footsteps gradually fade.
On screen, this is a single scene. In sound production, it consists of many separate elements. Someone must record or generate the voices, find the rain and train sounds, and adjust each element so it supports rather than obscures the dialogue. Even a temporary edit intended only to test the mood requires some of this work.
On September 22, Alibaba announced Qwen-Audio-3.1-TTS-Next, a model designed to generate these sounds together from a written script. Alibaba describes it as a way to combine dialogue and ambience into an audio scene, with potential applications in audiobooks, film and television, podcasts, and games.
From reading words aloud to building the sound of a scene
Text-to-speech usually brings to mind a straightforward process: enter a sentence and receive a spoken version of it. Qwen-Audio-3.1-TTS-Next aims to handle a broader task. A prompt can describe who is speaking, how they sound, what can be heard around them, and the order in which sounds appear.
Alibaba Cloud’s usage guide includes an example set on a railway platform. Alongside the characters’ voices and lines, the prompt describes rain hitting a metal roof, a distant train, the rustle of fabric, and receding footsteps. The guide advises users to distinguish spoken dialogue from scene directions and to specify how sounds should transition.
The notable change is more than the ability to add sound effects. The unit of instruction expands from a sentence to a scene. Instead of asking an AI to read a line in a low voice, a creator can describe what should remain audible after the line ends and what should happen next.
For video producers, this resembles storyboarding. A storyboard plans what viewers will see and how a shot will unfold. A sound prompt can plan what audiences will hear, in what order, and in relation to the action. Sound becomes part of the scene’s initial design rather than something considered only after the images have been assembled.
Where could it fit into production?
One plausible use is an early sound mock-up. During the development of a short film or advertisement, a director and editor may imagine the same scene differently. One may picture heavy rain dominating the soundtrack; the other may want the silence between the characters to carry more weight.
A short audio mock-up combining dialogue and ambience could give them something concrete to discuss. Before filming, it might help a team assess the sound concept. During an early edit, it could help them test whether the rhythm of the audio works with the images. Game and animation teams might also use it to explore the sound of a scene before final voice recording.
These are possible uses inferred from the announced capabilities, not measured production benefits. Whether the model saves time compared with assembling a temporary soundtrack, remains useful through repeated revisions, or aligns closely with a picture edit would require hands-on testing. The announcement alone does not establish a reduction in production time or cost.
Generating everything together is different from editing everything separately
In video production, revising sound matters as much as generating it. If rain masks a line, the rain must come down. If a shot becomes shorter, a footstep may need to move. An editor may preserve one distant sound while removing others to delay the audience’s discovery of someone outside the frame.
Alibaba says Qwen-Audio-3.1-TTS-Next generates audio that combines speech, effects, and ambience. The documentation reviewed here does not establish whether creators can receive those elements as separate tracks and edit each one independently. A convincing combined result and a soundtrack that remains flexible in postproduction are different things.
That distinction will matter in practice. Can a producer correct the pronunciation of one word without regenerating the scene? Can they lower only the train sound? Will a character’s voice remain consistent across multiple clips? The answers would determine how far the model can move beyond an initial mock-up. Its current documentation should not be presented as proof of that level of control.
Current limits for Korean-language production
The first specification Korean creators should check is language support. Alibaba Cloud lists Chinese and English for this model. It would therefore be inaccurate to say that it is ready for a Korean-language drama or advertisement. Support offered by another model in the Qwen family cannot be assumed to apply to Qwen-Audio-3.1-TTS-Next.
There are also limits on duration. According to the model documentation, a single request can produce up to four minutes for a podcast or up to two minutes for other scenarios. The input limit is 3,000 characters, and up to three reference audio clips can be supplied. Under these specifications, short scenes or segments are a more realistic unit of work than generating an entire feature-length soundtrack in one request.
Reference audio raises another practical question: whose voice will be used, and with what permission? A production team would also need to check whether the resulting voice stays consistent across scenes. When a real person’s recording is used as reference material, the ability to upload it does not remove the need to confirm permission and the intended scope of use.
How might the sound producer’s role change?
It is too early to conclude that creators will no longer need to record performances or source sound effects. Location recordings capture an actor’s performance and the acoustic character of a space. Sound editing involves placing individual sounds at precise moments and shaping variations across a scene. Whether a single generated audio file can serve those purposes has not yet been established.
The earlier stage of production could nevertheless change. Previously, a team might explain the desired sound, gather materials, assemble them, and only then hear a first approximation. A model that turns the description into an audio mock-up could let the team listen sooner. They could respond with more precise direction: “The rain is too prominent,” “Hold the silence longer after the line,” or “Bring in the footsteps later.”
The key skill would not simply be listing the sound effects a scene needs. It would be deciding what the audience should hear, and when. In the same railway scene, the train could make a farewell feel urgent, while a sudden break in the rain could make a character’s final words stand out. Sound supplies atmosphere, but it also controls how a story is revealed.
Qwen-Audio-3.1-TTS-Next offers a way to describe that sequence in writing and turn it into an audio draft. Its current language support, duration limits, and postproduction flexibility remain important qualifications. Its value in professional production will ultimately depend on how precisely creators can control and revise the sounds of an actual scene.
References: Alibaba Cloud announcement · Qwen-Audio-3.1-TTS-Next specifications · Audio generation guide